
Interpretability and the black hole interior: part I
November 10, 2026. Wherein black hole interiors are compared to neural networks.
Black holes, like neural networks, are hard to look inside: a black hole has a horizon, and a neural network is polysemantic, i.e., physical neurons fire for multiple features. As we show, the resemblance runs far deeper. In both cases, a large “effective” space is compressed by a linear map into a smaller space of “fundamental” degrees of freedom, forcing initially orthogonal directions to overlap, generating null states (the map has nontrivial kernel), and leading to phenomena like interference, superposition, and state-dependent operators. We show that, in both black holes and neural networks, the effective description is valid provided the map is random and confined to a narrow set of states, as measured by something called Gaussian width.
We use this condition to build a correspondence between the two domains, make quantitative predictions about neural feature recovery, and in later posts, confirm those predictions numerically in toy models of superposition. A collapsed star is a surprisingly accurate guide to the inside of a neural network!
Black holes
The quantum mechanics of black holes is a vast subject; for a review see Harlow’s Jerusalem Lectures. Thankfully, our focus is narrower: the holographic resolution of Hawking’s information paradox, and in particular, the insight of Akers, Engelhardt, Harlow, Penington and Vardhan (AEHPV) that the effective description of the black hole interior—the “bulk” local physics, given by creation and annihilation operators for quantum fields inside the horizon—is related to the fundamental description by a random linear compression. That’s a fancy term for a map from a bigger space to a smaller space.
We can describe the map more explicitly. The fundamental description consists of the black hole’s own unevaporated degrees of freedom $B$, counted by its entropy, together with the radiation it has emitted $R$; the compression acts on the interior modes alone. We illustrate the two descriptions in Figure 1. This compression accounts for several pieces of black hole folklore: the Page curve of the radiation entropy, the state-dependence of interior operators, the absence of low-complexity null states, and the exponential cost of decoding the radiation.
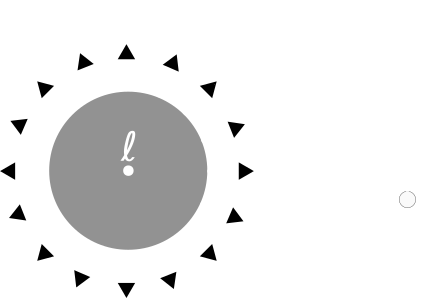
Figure 1. Two descriptions of a black hole.
Formally, we can ignore gravity and focus on the linear algebra of inner product spaces. The interior is effectively described by a Hilbert space $\mathcal H_\ell$ of dimension $|\ell|=e^{S_\ell}$, spanned by the states that the interior quantum fields can be in. The fundamental description of the black hole is a Hilbert space $\mathcal H_B$ of dimension $|B|=e^{S_{\rm BH}}$. At late times $S_\ell$ is much larger than the black hole’s Bekenstein–Hawking entropy $S_{\rm BH}$ because the interior keeps growing (more space means more ways to configure quantum states inside) while from the fundamental viewpoint, the black hole shrinks. The radiation is described by the same Hilbert space $\mathcal H_R$ in both pictures. Thus, the two descriptions are related by a linear map $V \otimes I_R$ for $V:\mathcal H_\ell\to\mathcal H_B$. Since $S_\ell > S_{\rm BH}$ at suitably late times, $V$ cannot be an isometry and must have nontrivial kernel, so some initially orthogonal vectors interfere; equivalently, some nonzero vectors in the effective description get annihilated and are called null states. We interpret the effective theory as breaking down on such states.
AEHPV cast $V$ in a more precise and suggestive form. Since black holes tend to randomly scramble whatever is thrown in, we can model their dynamics by choosing a unitary at random with unitarily-invariant measure, also called Haar measure. We build $V$ by first choosing a Haar-random unitary $U$ to act on the whole interior, consisting not only of the interior modes $\mathcal{H}_\ell$ but also the matter system $\mathcal{H}_f$ that collapsed to form the black hole in the first place. There is an alternative factorization of this joint space into the fundamental Hilbert space $\mathcal{H}_B$ and an auxiliary Hilbert space $\mathcal{H}_P$ of “fake” degrees of freedom needed to absorb the remainder:
\[\mathcal{H}_\ell\otimes \mathcal{H}_f = \mathcal{H}_B \otimes \mathcal{H}_P.\]Since dimension is multiplicative over a tensor product, this implies $|\ell| |f| = |B||P|$. We can then define $V:\mathcal H_\ell\to\mathcal H_B$ by projecting out the initial state of the collapsing system on the input side and a fixed state of the auxiliary $P$ on the output side:
\[V =\sqrt{|P|}\,\langle 0|_P\,U\,|\psi_0\rangle_f\,,\]where $|\psi_0\rangle_f$ represents the history of the black hole, $|0\rangle_P$ is an arbitrary fiducial state, and the prefactor $\sqrt{|P|}$ normalizes $V$ to be an approximate isometry.
For convenience, we work with $|f| = 1$ but the statements generalize immediately to nontrivial $|f|$. Setting $M=|\ell|$ and $N=|B|$, and observing that $V$ is simply $N$ rows of an $M \times M$ Haar-random unitary $U$, we can simplify to
\[V=\sqrt{\frac{M}{N}}\,\Pi_N U\]for a projection $\Pi_N$ onto those rows. Although $V$ cannot be an isometry—it collapses a large space into a small one—it is an approximate isometry in three increasingly robust ways:
-
Overlaps are preserved on average:
\[\mathbb{E}_V\langle\psi|V^\dagger V|\phi\rangle = \langle \psi|\phi\rangle;\] -
The fluctuations are exponentially small in the black hole entropy, $S_{\rm BH} = \log N$:
\[\mathbb E_V\big|\langle\psi |V^\dagger V |\phi\rangle-\langle \psi|\phi\rangle\big|^2=\frac{(M-N)\,(M-|\langle\psi|\phi\rangle|^2)}{N\,(M^2-1)} =\mathcal{O}\left(e^{-S_{\rm BH}}\right);\] -
Deviations cannot be detected by “simple” states, i.e., if $\Sigma_C\subseteq\mathcal H_\ell$ denotes states prepared by quantum circuits of at most $C$ gates, then with overwhelming likelihood,
\[\sup_{\psi,\phi\in\Sigma_C}\big|\langle\psi| V^\dagger V|\phi\rangle-\langle\psi|\phi\rangle\big|\lesssim\sqrt{C\log S_\ell}\;e^{-S_{\rm BH}/2}.\]
Thus, $V$ is an isometry on average, with small departures, requiring exponentially complex (in $S_{\rm BH}$) experiments to detect. This implies that it is exponentially difficult to detect null states, so the theory remains effectively valid for low complexity observers. Conversely, an effective operator $A: \mathcal{H}\ell \to \mathcal{H}\ell$ determines a state-dependent fundamental operator via the equation
\[A_\phi V |\phi\rangle = VA |\phi\rangle,\]with suppressed fluctuations on low complexity states:
\[\sup_{\phi\in\Sigma_C}\big|\langle\phi| V^\dagger B_\phi^\dagger A_\phi V|\phi\rangle-\langle\phi|B^\dagger A|\phi\rangle\big|\lesssim c_{AB}\sqrt{C\log S_\ell}\;e^{-S_{\rm BH}/2}.\]This follows immediately from the third bullet above. In contrast, the state-independent operator $V A V^\dagger$ does not enjoy this property: it is wrong even on average. Since $VV^\dagger = \frac{M}{N} I_N$, taking $A = I$ for instance gives
\[\langle\phi|V^\dagger (V IV^\dagger) V|\phi\rangle =\frac{M}{N}\langle\phi|V^\dagger V|\phi\rangle \approx \frac{M}{N},\]which grows with $M = e^{S_{\ell}}$. Evidently, these are not the operators we’re looking for.
Neural networks
The working hypothesis of mechanistic interpretability (Olah et al. 2020) is that a trained network computes with features: directions in activation space that correspond to human-legible properties of the input, such as “the text is in Farsi” or “the signal light is red”. A network is understood when its features and the circuits connecting them have been named. The obstacle is that features are not neurons, since a single neuron typically responds to several unrelated features, and a single feature is spread across many neurons. This is called polysemanticity, and it is the sense in which a neural network is hard to look inside.
Elhage et al. observe that polysemanticity is just the flip side of compression. A network that needs to represent $m$ features in a layer of $n<m$ neurons cannot assign each feature its own neuron. But if the features are sparse—few are active on any given input—it can instead assign each feature a direction in $\mathbb R^n$ and accept that the directions overlap, because the overlaps only matter when the overlapping features are simultaneously active, an occurrence that sparsity makes rare. This is superposition: the network simulates a larger, monosemantic network in which every feature has its own neuron. The effective description is that larger network; the fundamental description is the one with $n$ neurons that is physically instantiated; the relation between them is a linear compression from feature space to activation space.
Figure 2. Two descriptions of a neural network.
Formally, we can forget about training or architecture and focus entirely on the linear algebra of inner product spaces. The effective description is a feature space $\mathbb R^m$, with one coordinate per feature; a feature activation $x\in\mathbb R^m$ is nonzero on a small set of coordinates, and we write $\Sigma_k$ for the unit vectors with at most $k$ nonzero entries. The fundamental description is the activation space $\mathbb R^n$ of a layer with $n<m$ neurons. The two are related by a linear map
\[W\colon\mathbb R^m\to\mathbb R^n,\qquad h=Wx,\]whose columns $w_1,\dots,w_m$ are the feature directions; the network readout is a decoder $\hat x=D(h)$, which in the simplest case is $\text{ReLU}(W^\top h+b)$. Since $m>n$, $W$ cannot be an isometry: its kernel has dimension at least $m-n$, and feature space contains a vast subspace of “null” activation patterns the layer ignores.
We work with a random model in which the entries of $W$ are independent Gaussians of variance $n^{-1}$. In this model, we have an approximate isometry $W: \mathbb{R}^m \to \mathbb{R}^n$ in three senses:
-
Overlaps are preserved on average,
\[\mathbb E_W\langle {W\hat{x}},{W\hat{y}}\rangle=\langle \hat{x}, \hat{y}\rangle;\] -
Fluctuations are suppressed in the number of neurons,
\[\mathbb E_W\,\big(\langle{W\hat{x}},{W\hat{y}}\rangle-\langle \hat{x}, \hat{y}\rangle\big)^2=\frac{1+\langle\hat{x},\hat{y}\rangle^2}{n}=\mathcal{O}(n^{-1});\] -
Finally, with overwhelming probability, fluctuations are small for $k$-sparse feature vectors,
\[\sup_{\hat{x},\hat{y}\in\Sigma_k}\big|\langle{W\hat{x}},{W\hat{y}}\rangle-\langle \hat{x},\hat{y}\rangle\big|\lesssim\sqrt{\frac{k\log(em/k)}{n}}.\]
An input vector can therefore be described by independent features unless it is network-wide, i.e. has $k = \mathcal{O}(n)$ entries. We can perform linear computations with these input vectors by defining $W A \hat{x} = A_x W \hat{x}$. The third bullet point immediately gives
\[\sup_{\hat{x}\in\Sigma_k}\big|\langle{A_xW\hat{x}},{B_xW\hat{x}}\rangle-\langle A\hat{x},B\hat{x}\rangle\big|\lesssim d_{AB}\sqrt{\frac{k\log(em/k)}{n}}.\]In contrast, the conjugate $WAW^\top$ is not $A$ on average. Since $WW^\top \approx \frac{m}{n} I_n$, setting $A = I$ gives
\[\langle{WW^\top W\hat{x}},{W\hat{x}}\rangle \approx \frac{m}{n}\Vert W\hat{x}\Vert^2 \approx\frac{m}{n}.\]Thus, mapping effective operators on independent features to physical neurons can only be done in an input-dependent way.
Overview
Interpretability and the black hole interior have a common pattern: a linear map $\Omega: S \to T$ from $S$ to a smaller space $T$, $|S| > |T|$, which with high likelihood is approximately isometric when restricted to a “simple” set $\Sigma$. The spaces in question are complex for black holes ($\mathbb{F}=\mathbb{C}$) and real for interpretability ($\mathbb{F}=\mathbb{R}$). Define the distortion $\mathscr{D}_\Omega(\Sigma)$ on the set $\Sigma$ by
\[\mathscr{D}_\Omega(\Sigma) = \sup_{\hat{\alpha},\hat{\beta}\in\Sigma} \left\vert \langle \Omega\hat{\alpha}, \Omega\hat{\beta}\rangle - \langle\hat{\alpha}, \hat{\beta}\rangle\right\vert,\]and observe that in both cases, random maps yield $\mathscr{D}\Omega(\Sigma) = \mathcal{O}(\sqrt{C\Sigma \log|S|/|T|})$ with high probability.
A simple theorem generalizes this common pattern. First, we select a linear compression at random, meaning $\Omega$ is a random matrix chosen according to a $U(S)$-invariant measure (when $\mathbb{F}=\mathbb{C}$) or $O(S)$-invariant measure (when $\mathbb{F}=\mathbb{R}$). Next, we need to characterize which sets are “simple”. Define the Gaussian width $\mathscr{W}(\Sigma)$ of $\Sigma$ by
\[\mathscr{W}(\Sigma) = \mathbb{E}\left[\sup_{z\in \Sigma} \langle g, z\rangle\right], \quad g \sim \mathcal{N}(0, I_{|S|}),\]the expected largest overlap with a standard Gaussian.
Theorem (informal). With overwhelming probability, distortion is upper bounded by width over the square root of $|T|$:
\[\mathscr{D}_\Omega(\Sigma) \lesssim \frac{\mathscr{W}(\Sigma)}{\sqrt{|T|}}, \quad \text{provided }\mathscr{W}(\Sigma)^2\ll |T|,\]where $\lesssim$ hides additive and multiplicative constants and $\Omega$ is Haar-random.
Both the sets given above—those of low complexity $\Sigma_C$ and $k$-sparse $\Sigma_k$—obey $\mathscr{W}(\Sigma)^2\ll |T|$ via a union bound, and hence give a normalized bound to the distortion. Thus, the theorem subsumes both types of approximate isometry. Approximate isometry invites the attempt to decode. Rewriting the distortion as
\[\mathscr{D}_\Omega(\Sigma) = \sup_{\hat{\alpha},\hat{\beta}\in\Sigma} \left\vert \langle \hat{\alpha}, (\Omega^*\Omega - I)\hat{\beta}\rangle\right\vert,\]where $$ denotes either adjoint ($\mathbb{F}=\mathbb{C}$) or transpose ($\mathbb{F}=\mathbb{R}$), the naive inversion map is $\Omega^$. But the problem with this inversion is that it only works on test vectors in $\Sigma$, and may fail badly away from this set. We can write a general form
\[\Omega^* \Omega \hat{\gamma} = \hat{\gamma} + \epsilon(\hat{\gamma}),\]with $\epsilon(\hat{\gamma})$ approximately orthogonal to $\Sigma$ whenever $\hat{\gamma}\in \Sigma$. Because of this error, reconstruction depends on $\hat{\gamma}$; we have to choose some method (such as projection onto a choice of $\Sigma$) to eliminate it. Both cases use a state-dependent generalization of the transpose: Petz recovery in the black hole case, and one-step thresholding in the neural network.